- Marketing Analytics and Data
- September 15, 2026
- 52 views

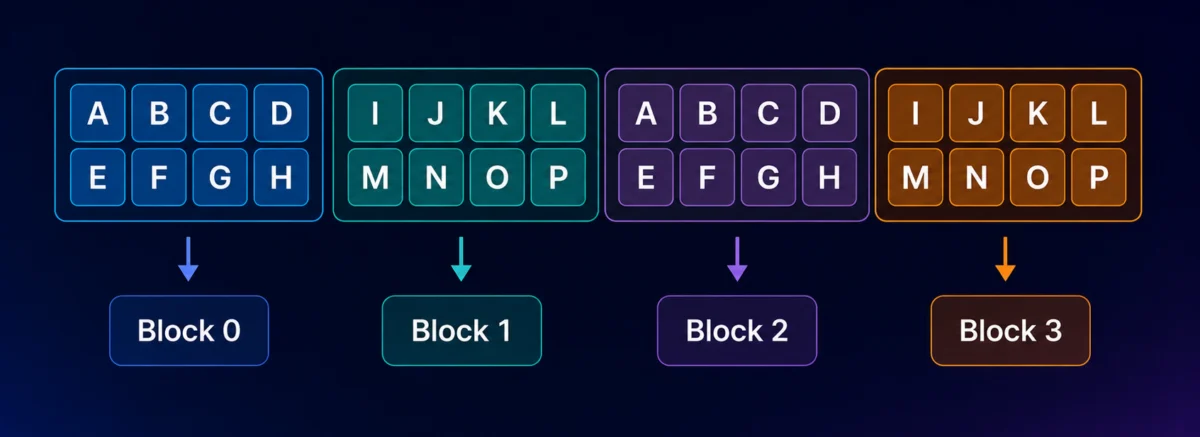
Optimizing Large Language Model Performance: A Technical Deep Dive into KV, Prefix, Prompt, and Semantic Caching Strategies
The rapid expansion of Large Language Model (LLM) applications into enterprise-grade workflows has brought the dual challenges of inference latency and operational costs to the forefront of the artificial intelligence…
- Marketing Analytics and Data
- September 8, 2026
- 47 views
A Comprehensive Guide to LLM Caching Techniques: Optimizing Inference Performance and Cost Efficiency
As Large Language Model (LLM) applications transition from experimental prototypes to enterprise-grade production systems, the focus of the artificial intelligence industry has shifted toward the dual challenges of inference latency…