 Muslim
In the rapidly evolving landscape of artificial intelligence, the transition from simple chatbots to autonomous coding agents has highlighted a significant technological hurdle: the lack of persistent, cross-session memory. While large language models (LLMs) have gained increasingly expansive context windows, capable of processing hundreds of thousands of tokens at once, they remain fundamentally "stateless" between individual chat sessions. This limitation often results in agents repeating past mistakes, failing to adhere to newly established team protocols, and requiring redundant instructions for every new task. TencentDB Agent Memory, a newly released open-source project from Tencent, addresses this gap by providing a managed, multi-layered memory architecture designed specifically for collaborative AI environments.
The core challenge facing modern AI agents is not merely the volume of information they can process, but the retention and application of "lessons learned." In a typical software engineering workflow, an AI agent might spend hours debugging a complex payment gateway issue on a Monday, identifying specific edge cases and establishing a unique fix. However, when a new session begins on Tuesday to address a similar bug, the agent—operating with a fresh context—reverts to outdated runbooks and standard procedures, effectively "forgetting" the critical breakthroughs made 24 hours prior. TencentDB Agent Memory seeks to transform these fleeting interactions into durable, reusable assets that can be shared across a team of agents in a controlled and secure manner.
The Limitation of Context Windows in Team Environments
The industry has long viewed the expansion of context windows as the primary solution for AI memory. However, technical analysis suggests that "longer prompts" do not equate to "better memory." Raw chat transcripts are often noisy, containing irrelevant banter, false starts, and temporary decisions that should not be codified into long-term policy. Furthermore, a massive context window does not provide a mechanism for determining which information remains current or who is authorized to view it.
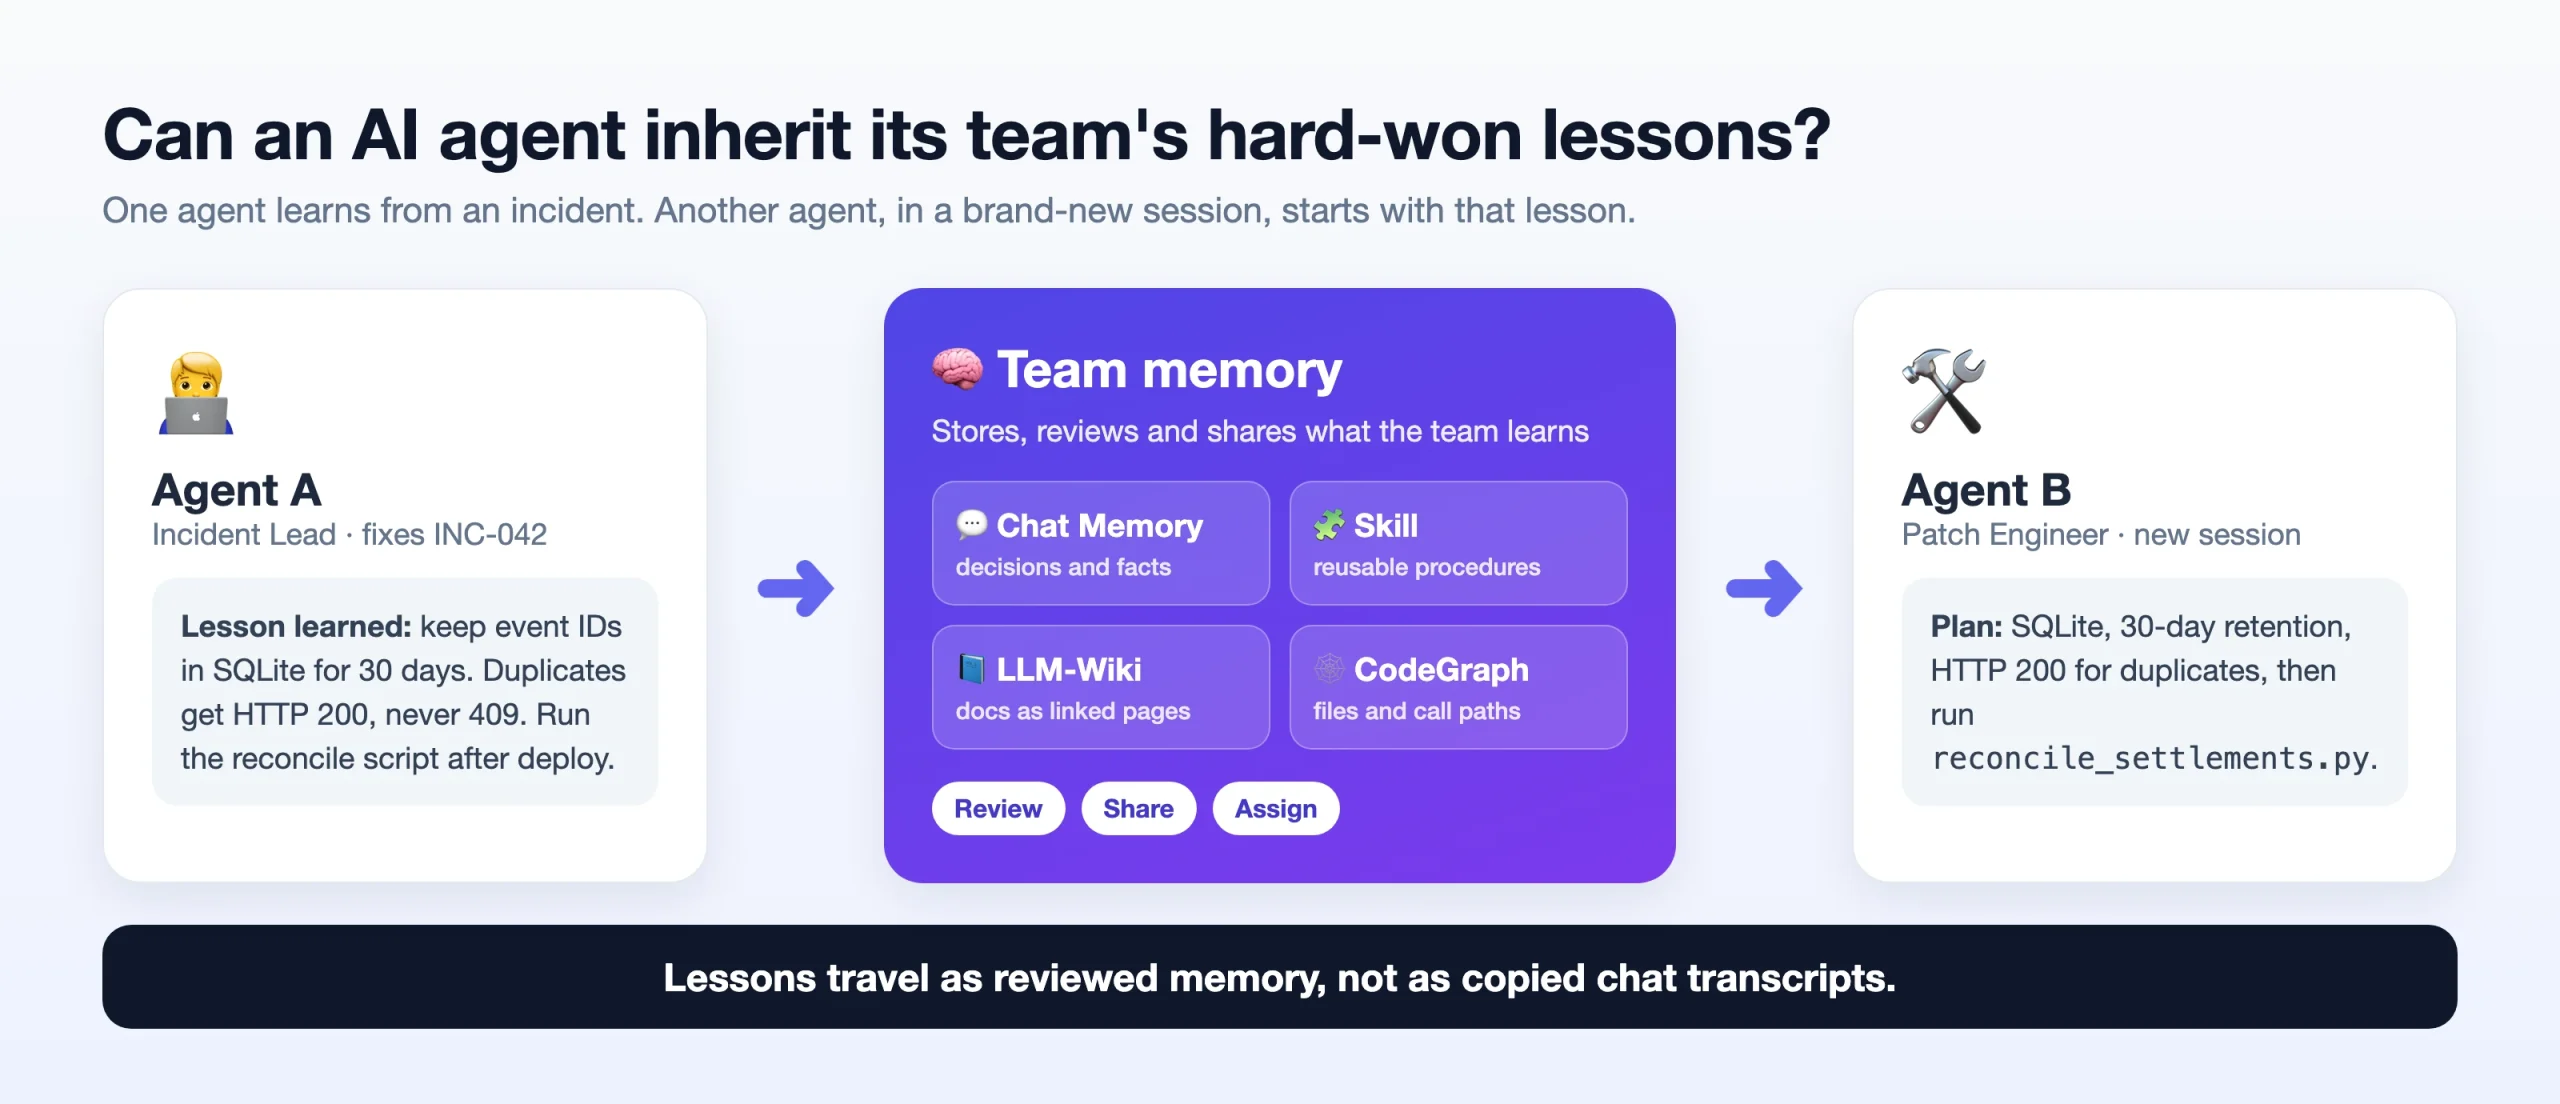
In a professional setting, information density and privacy are paramount. A release reviewer requires access to incident history and checklists, while a code-writing agent needs a map of affected functions. Conversely, a customer support agent should not be exposed to internal code vulnerabilities. By loading an entire history into an agent’s context window, developers inadvertently introduce "noise" that can degrade the model’s reasoning performance and risk leaking sensitive data. TencentDB Agent Memory moves away from this "everything-at-once" approach, treating memory as managed assets with specific owners, visibility levels, and lifecycles.
Architectural Framework: The Four Pillars of Agent Memory
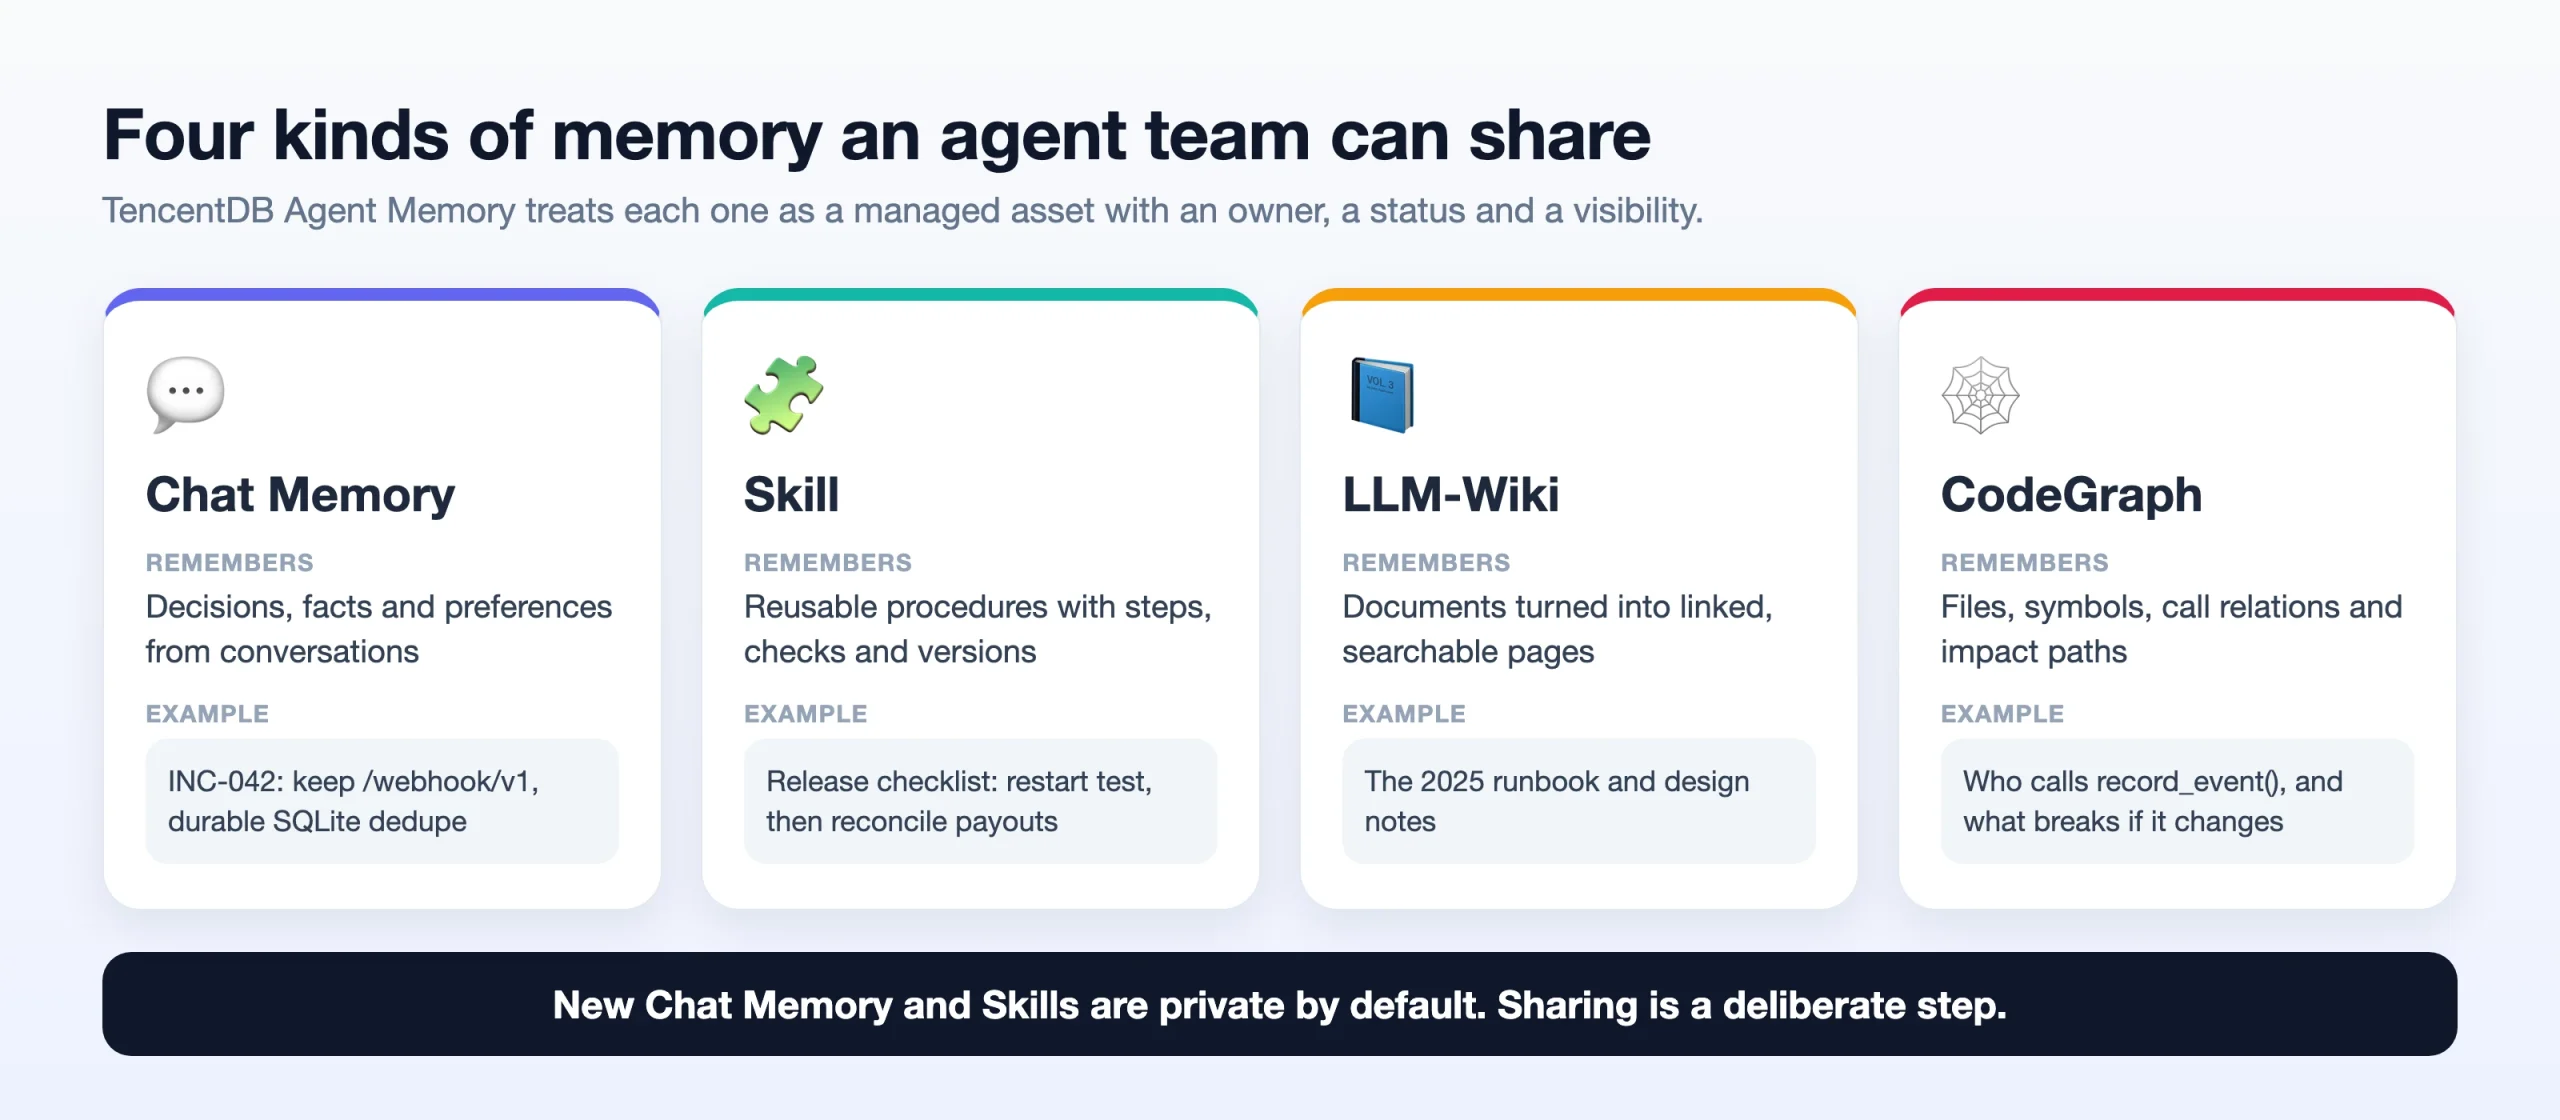
The TencentDB Agent Memory project categorizes shared knowledge into four distinct asset types, each serving a specific role in the engineering lifecycle.
1. Chat Memory
This layer captures the nuances of human-agent and agent-agent conversations. Instead of requiring a user to paste an entire historical transcript, Chat Memory stores specific decisions, facts, and user preferences. This allows an agent to "restore" the context of a previous incident without the overhead of irrelevant dialogue.
2. Skills
Skills represent the evolution of a successful debugging session into a repeatable procedure. When an agent identifies a successful sequence of steps to resolve a bug, that sequence can be saved as a "Skill." These skills include specific checks and versioning, effectively turning the agent’s experience into a structured release checklist or runbook.
3. LLM-Wiki
Traditional documentation is often difficult for AI agents to navigate efficiently. The LLM-Wiki component transforms static documents into linked, searchable pages. This ensures that when an agent is tasked with a procedure, it can find the exact relevant runbook rather than scanning an entire documentation repository.
4. CodeGraph
Perhaps the most technical of the assets, the CodeGraph maps the relationships between files, symbols, and call paths. It allows an agent to perform "impact analysis" before making a change, seeing which functions will be affected by a modification. This level of structural awareness is rarely found in standard RAG (Retrieval-Augmented Generation) systems.
The Hierarchy of Recall: From L0 to L3
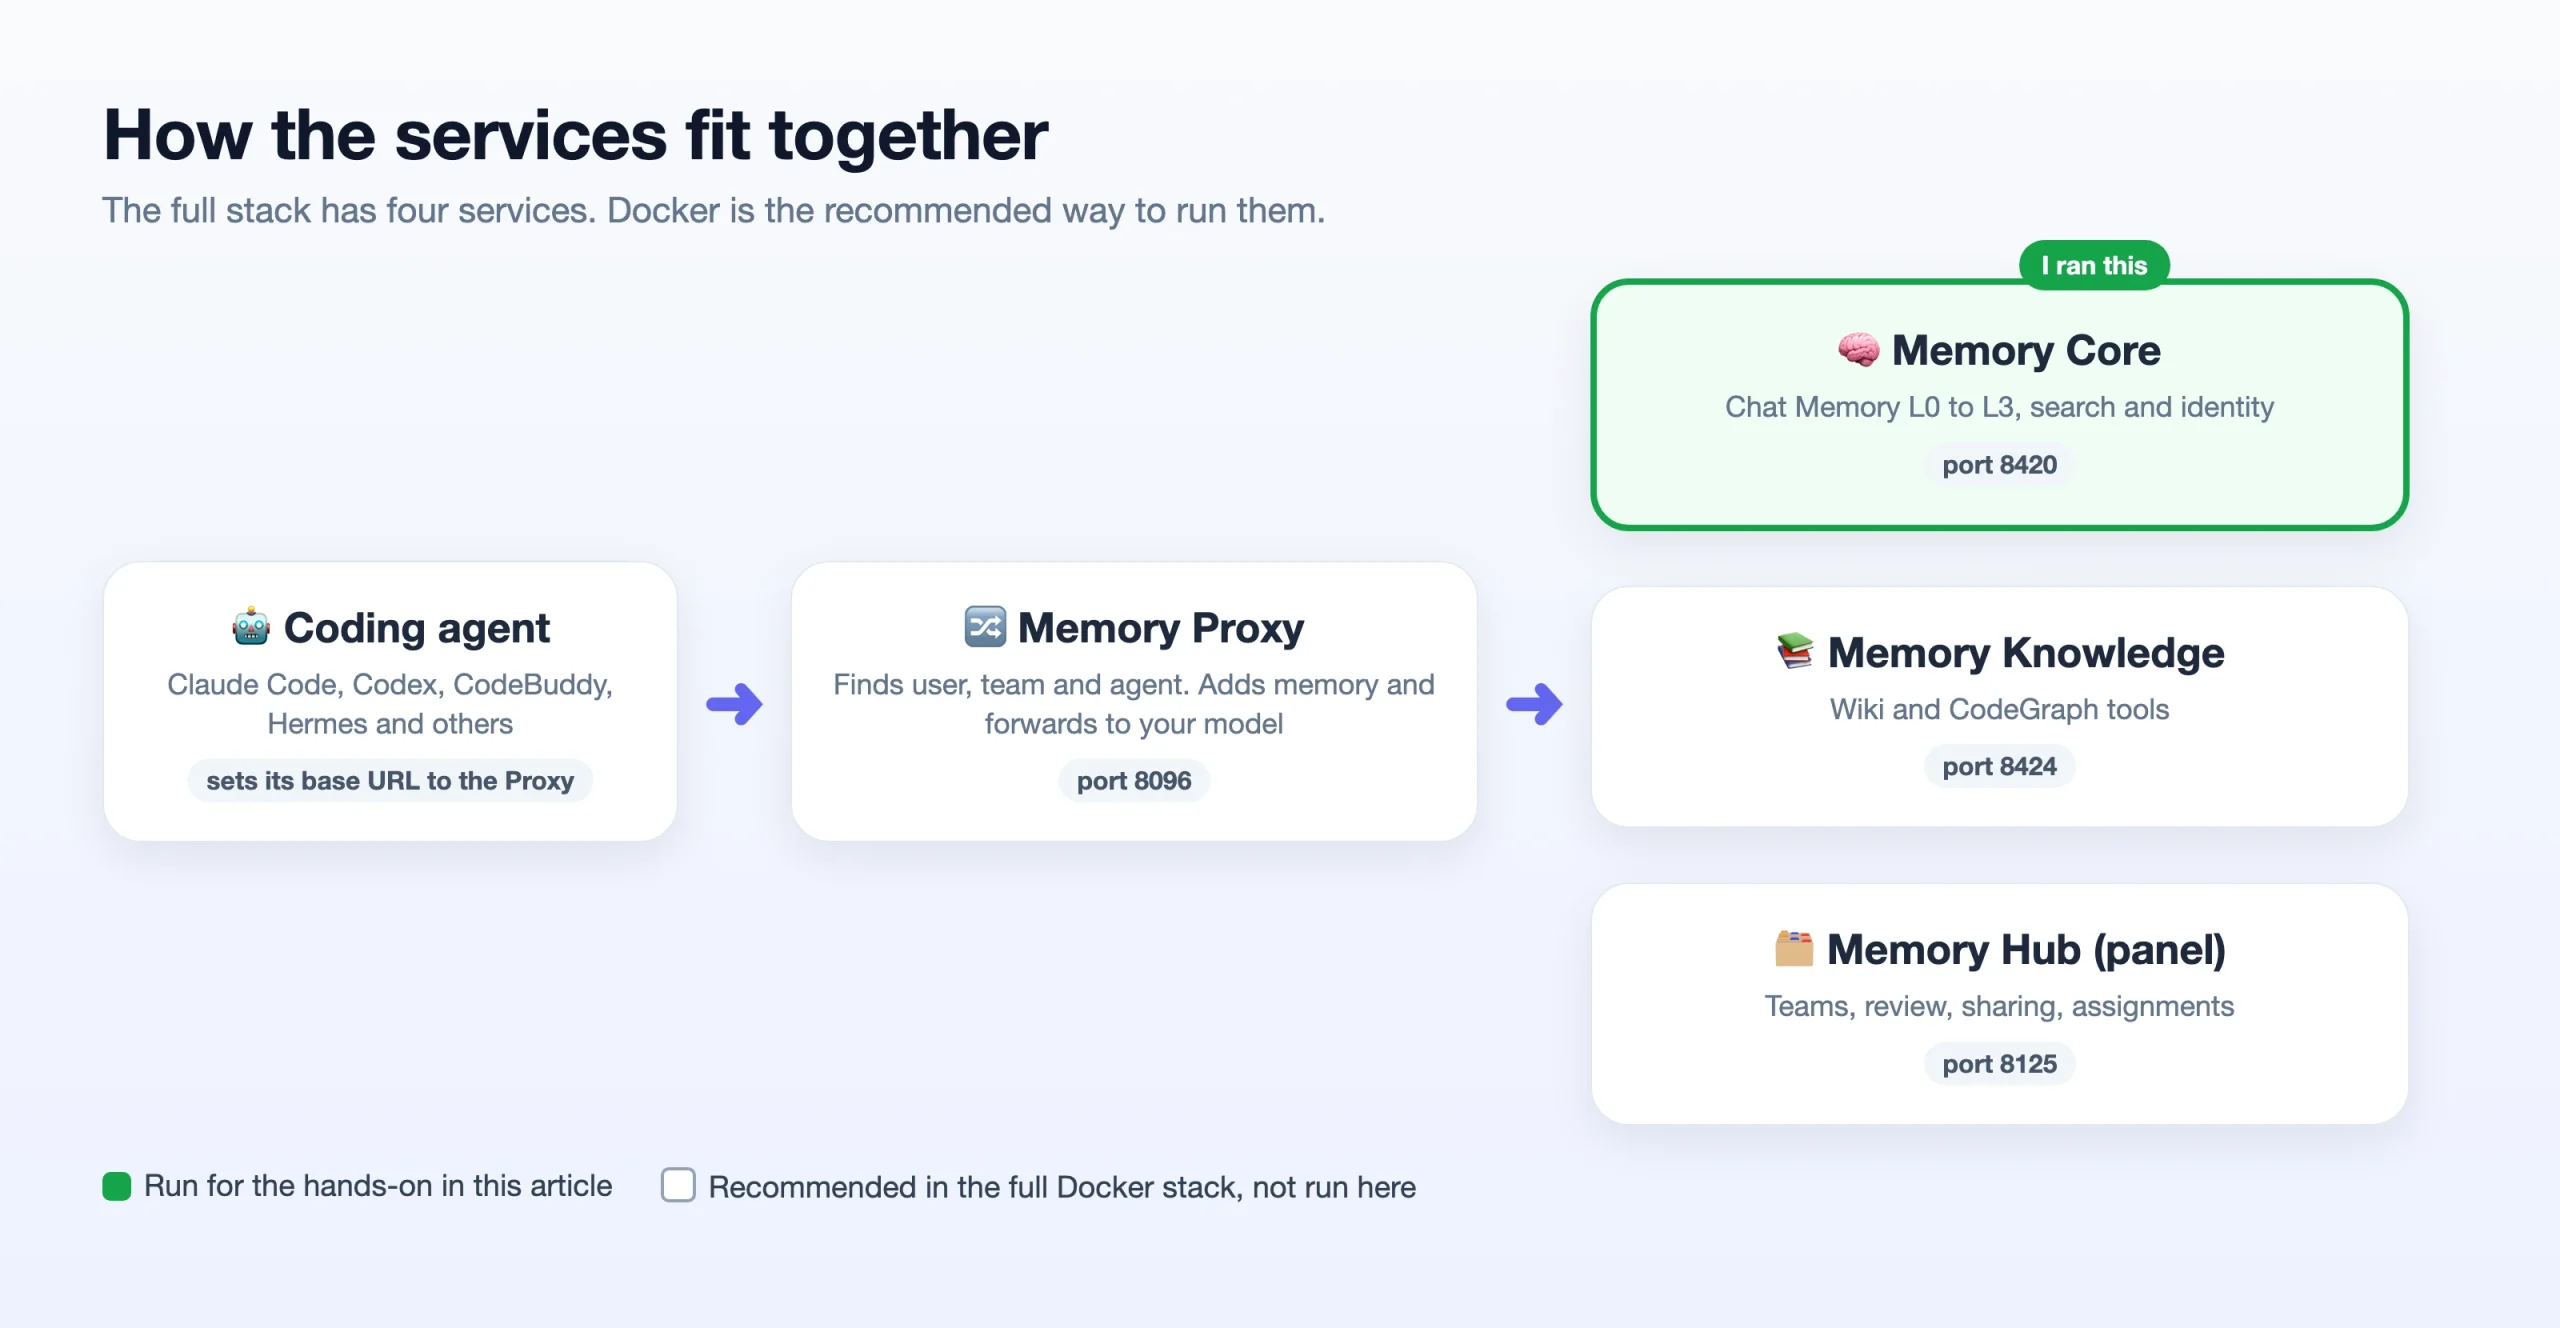
Tencent’s approach to memory is hierarchical, ensuring that retrieval is both fast and accurate. The system operates across four layers of abstraction:
- L0 (Raw Conversation): The base layer containing the original, unedited dialogue. This serves as the "source of truth" if the agent needs to verify the original wording of a decision.
- L1 (Atomic Facts): Known as "atoms," these are extracted facts distilled from the raw conversation (e.g., "The timeout limit was increased to 30 seconds").
- L2 (Scenario Knowledge): This layer groups knowledge around specific projects or scenarios, providing a mid-level context for the agent.
- L3 (Stable Patterns): The highest layer, containing long-term profiles and stable operational patterns that rarely change.
When an agent queries the system, it uses a combination of BM25 keyword search and vector search, merged via Reciprocal Rank Fusion (RRF). This ensures that the agent receives the most relevant context while staying within a predefined token budget. Crucially, this is not a model-training process. The LLM does not "learn" in the traditional sense; instead, the memory is stored externally and retrieved as needed, ensuring that the system remains flexible and that information can be deleted or updated instantly.
Chronology of an Experiment: Validating Persistent Memory
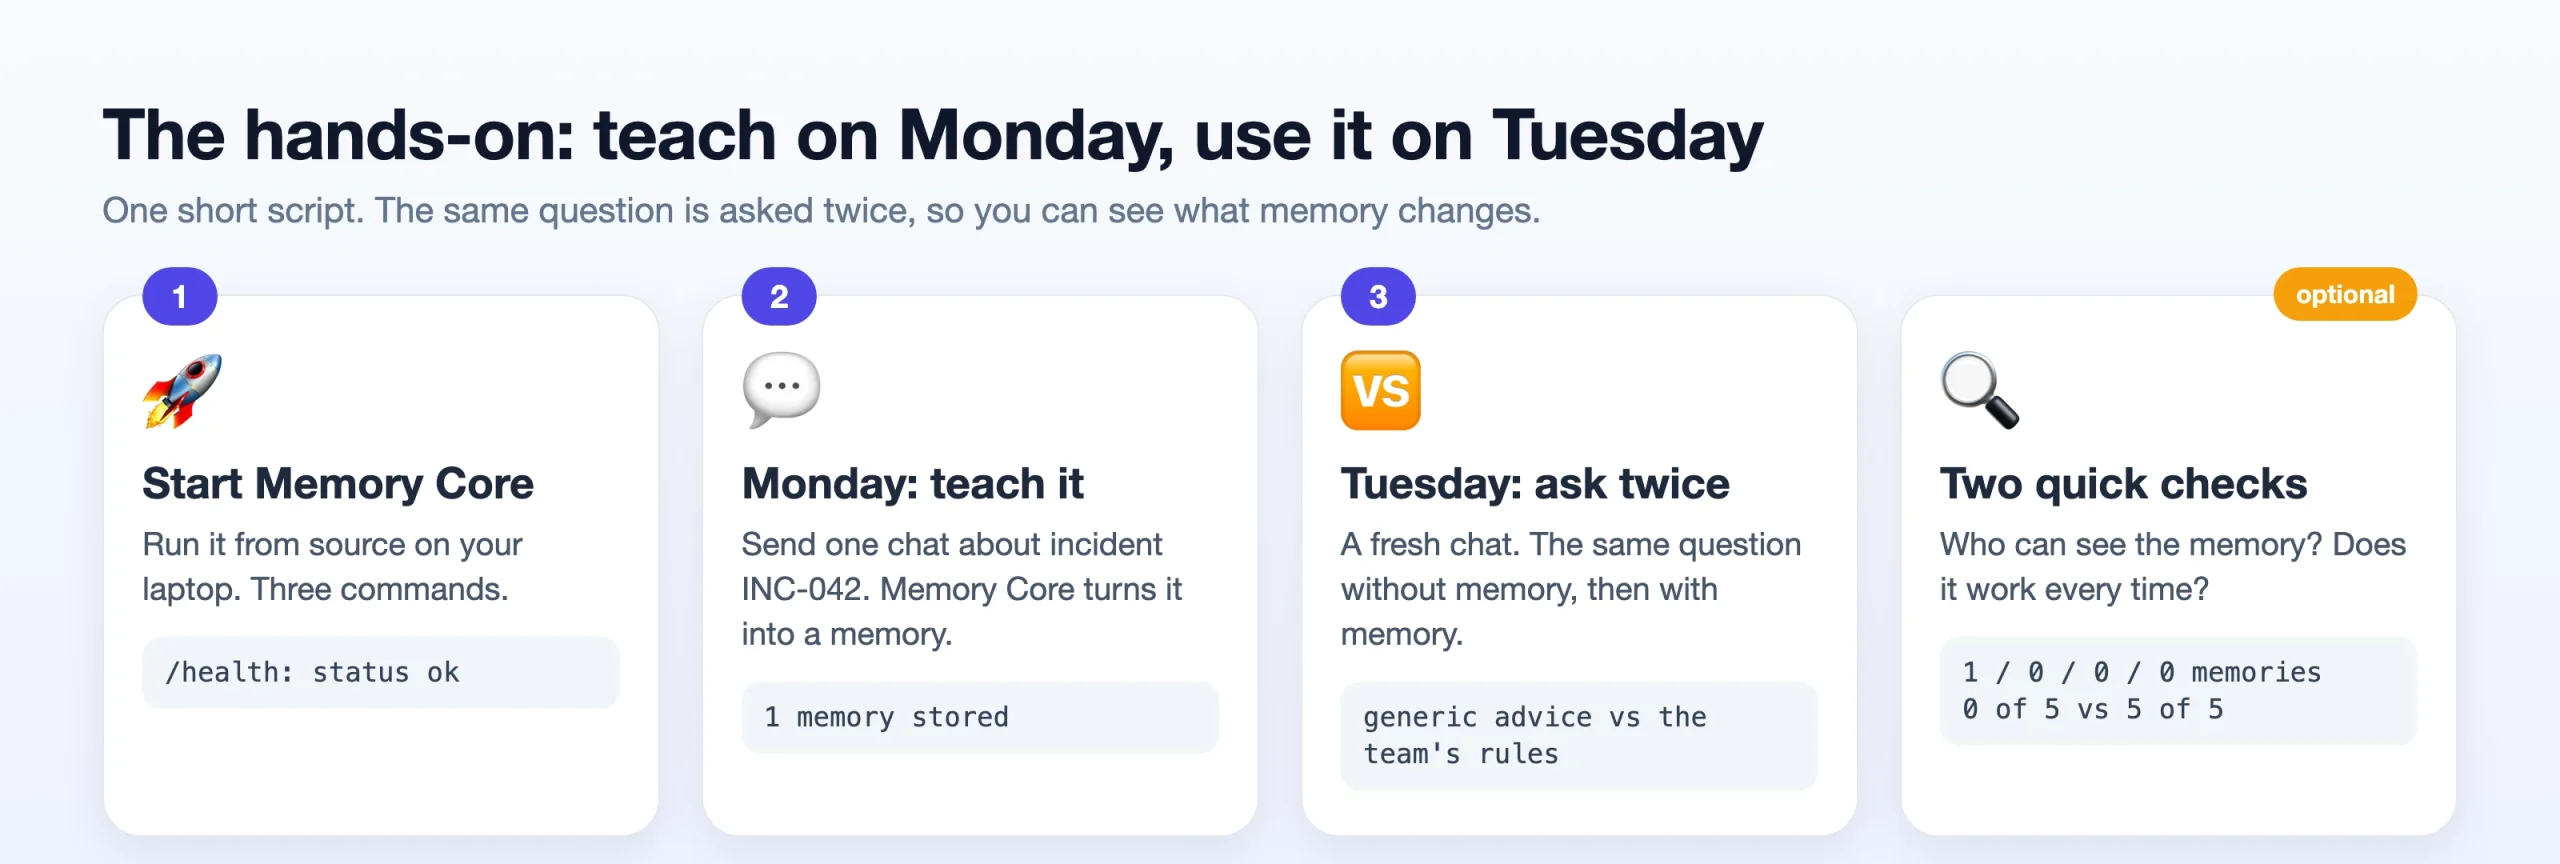
To demonstrate the efficacy of the system, technical observers conducted a two-day experiment simulating a real-world production incident.
Monday: The Learning Phase
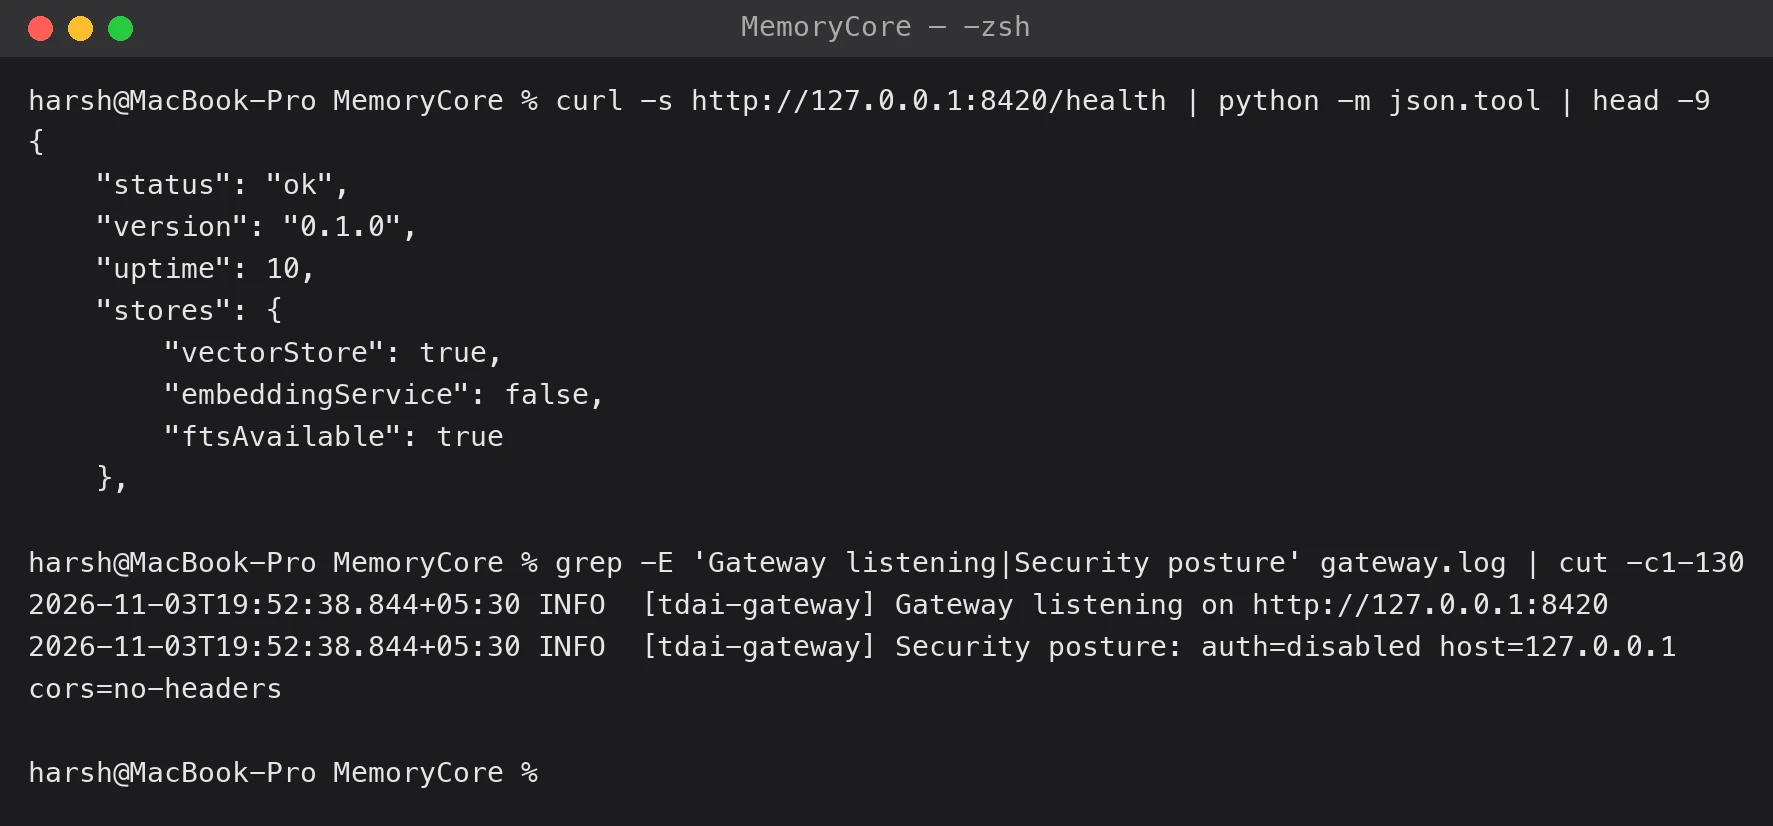
An engineering team addressed a production incident (INC-042) where a partner was double-paid following a webhook worker restart. During the resolution, the team established three critical rules: retain event IDs for 30 days, respond to duplicates with HTTP 200 (not 409) to prevent infinite retries, and run a specific reconciliation script. This conversation was fed into the Memory Core.
Tuesday: The Retrieval Phase
A brand-new chat session was initiated with a different agent identity. The agent was asked how to handle duplicate payouts after a webhook restart. In the control group (without memory), the AI provided a generic response, suggesting standard debugging steps but missing the specific organizational protocols established on Monday. In the experimental group (with TencentDB Agent Memory), the agent correctly identified the 30-day retention rule, the HTTP 200 requirement, and the specific reconciliation script name.
This experiment highlighted a critical finding: the model’s performance was not limited by its intelligence, but by its access to historical context. By bridging the gap between sessions, the AI moved from being a "generic assistant" to a "team-aware engineer."
Security, Access Control, and Performance Data
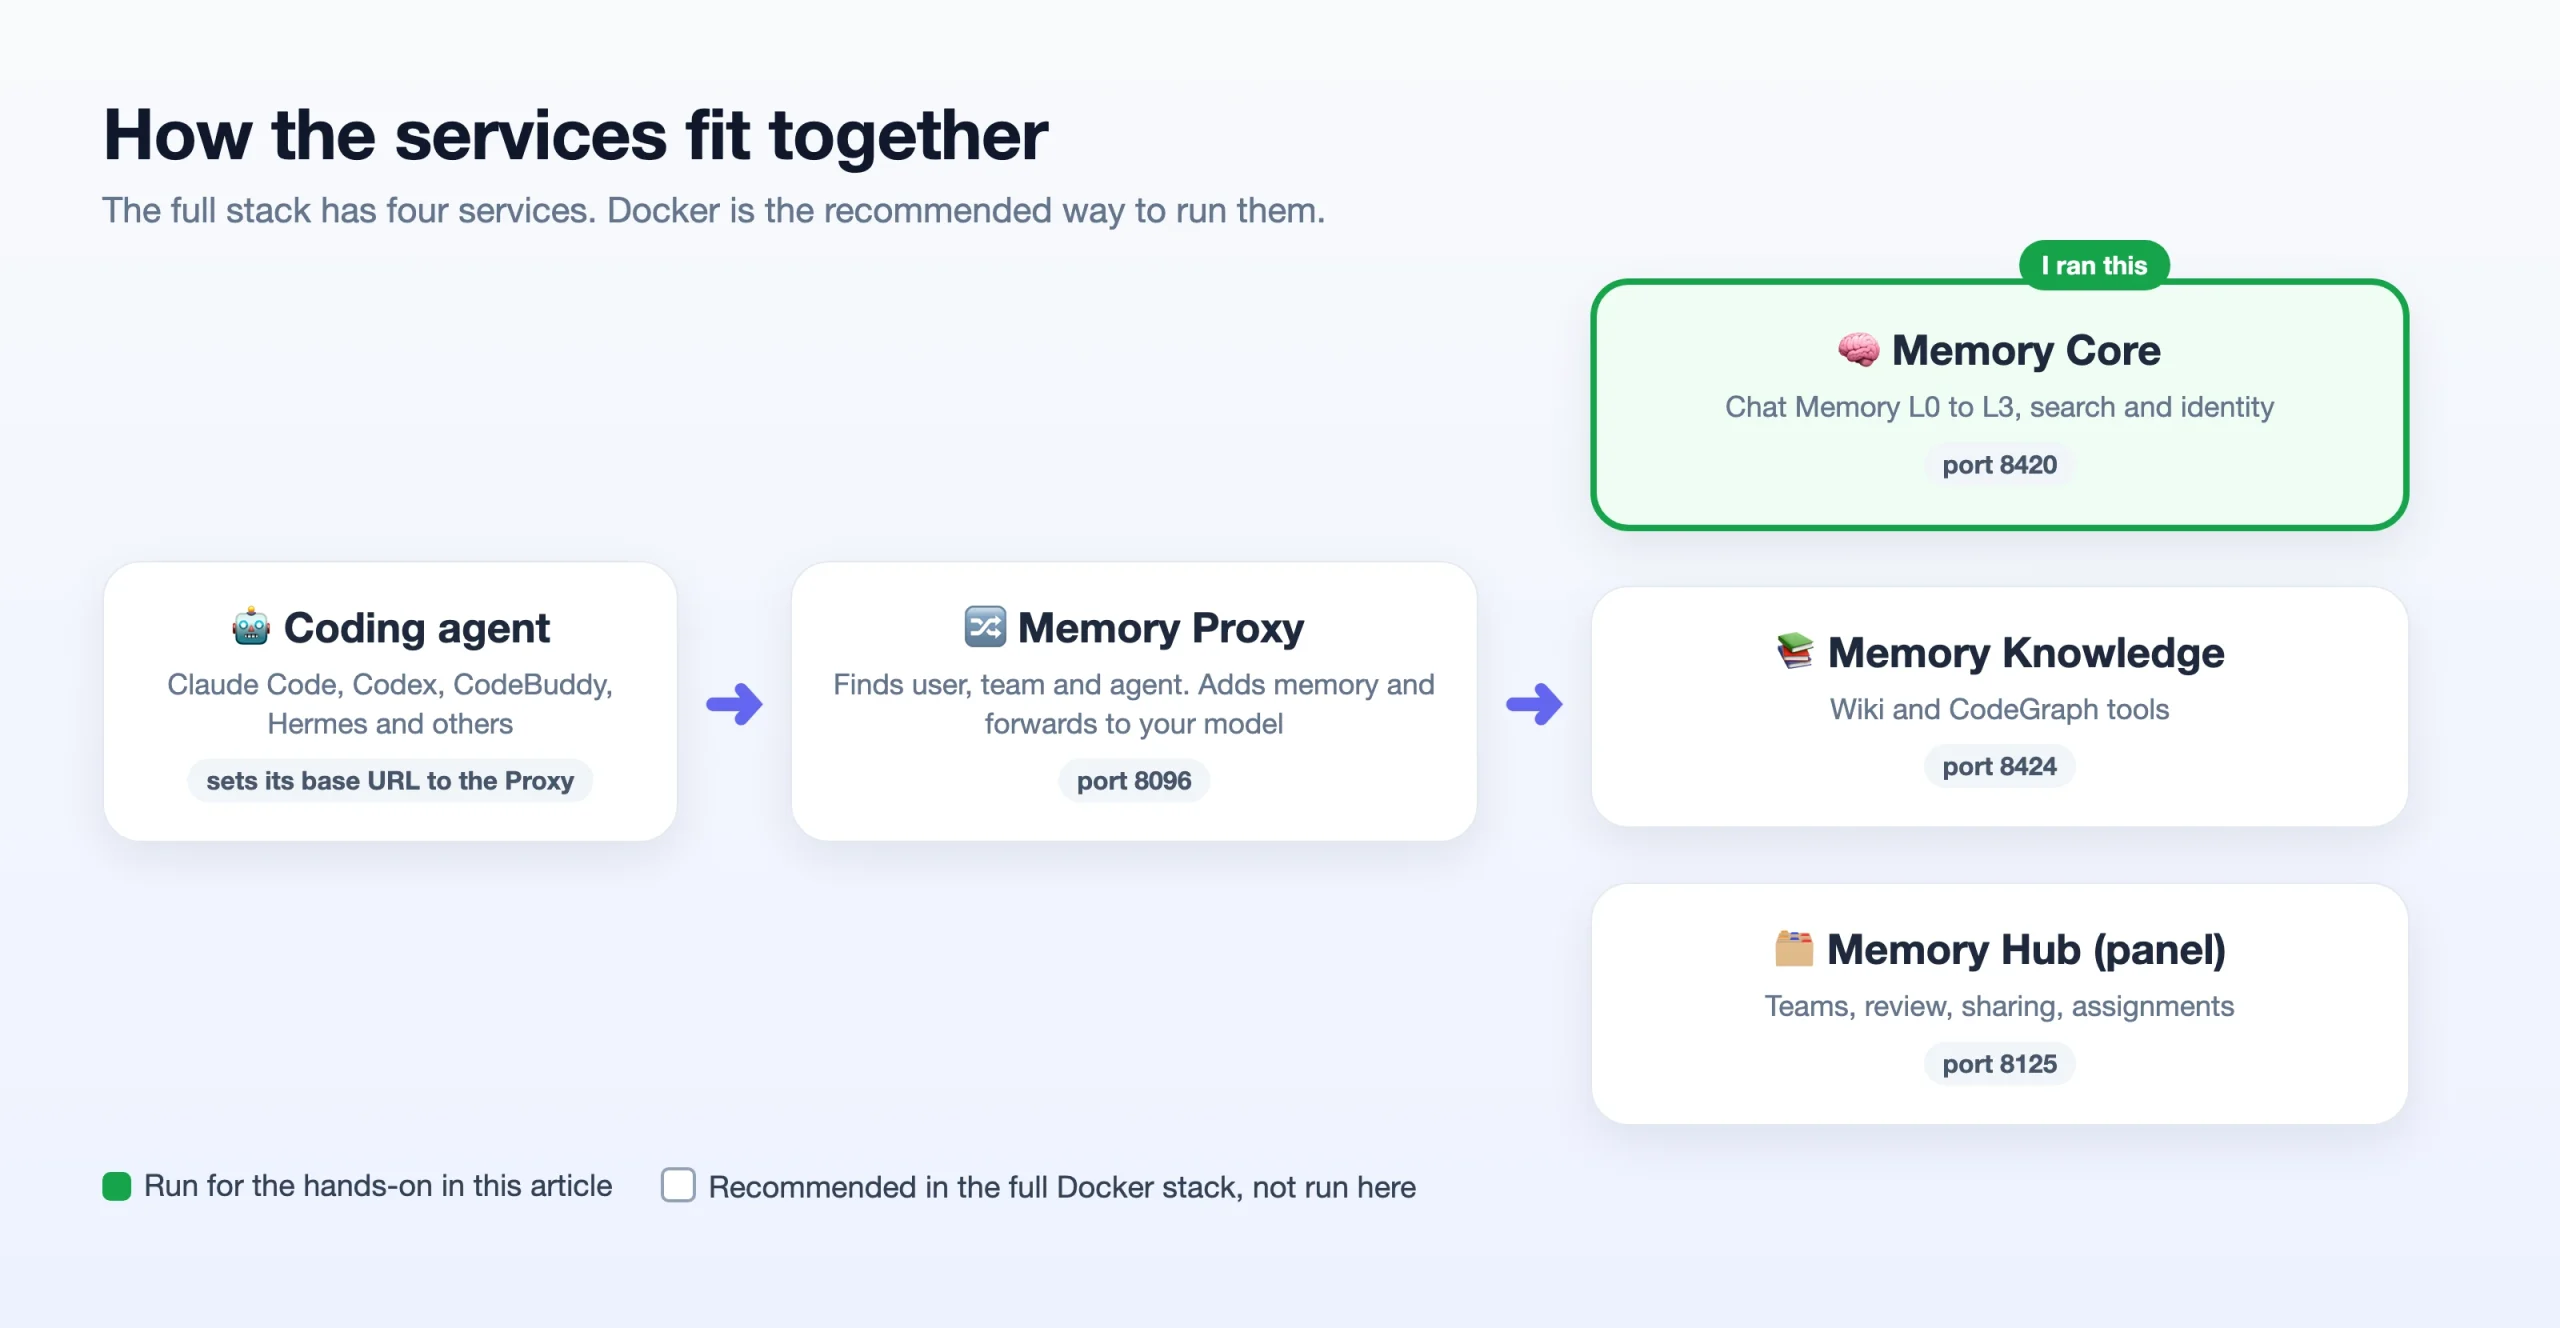
A significant portion of the TencentDB Agent Memory project is dedicated to the "Memory Hub," a web-based panel for team management. In professional environments, the "visibility" of a memory is as important as the memory itself. The project defines four visibility levels:
- Private: Accessible only to the owner.
- Team: Shared across a specific organizational unit.
- Restricted: Governed by specific access rules for roles or users.
- Agent: Specifically assigned to certain AI agents.
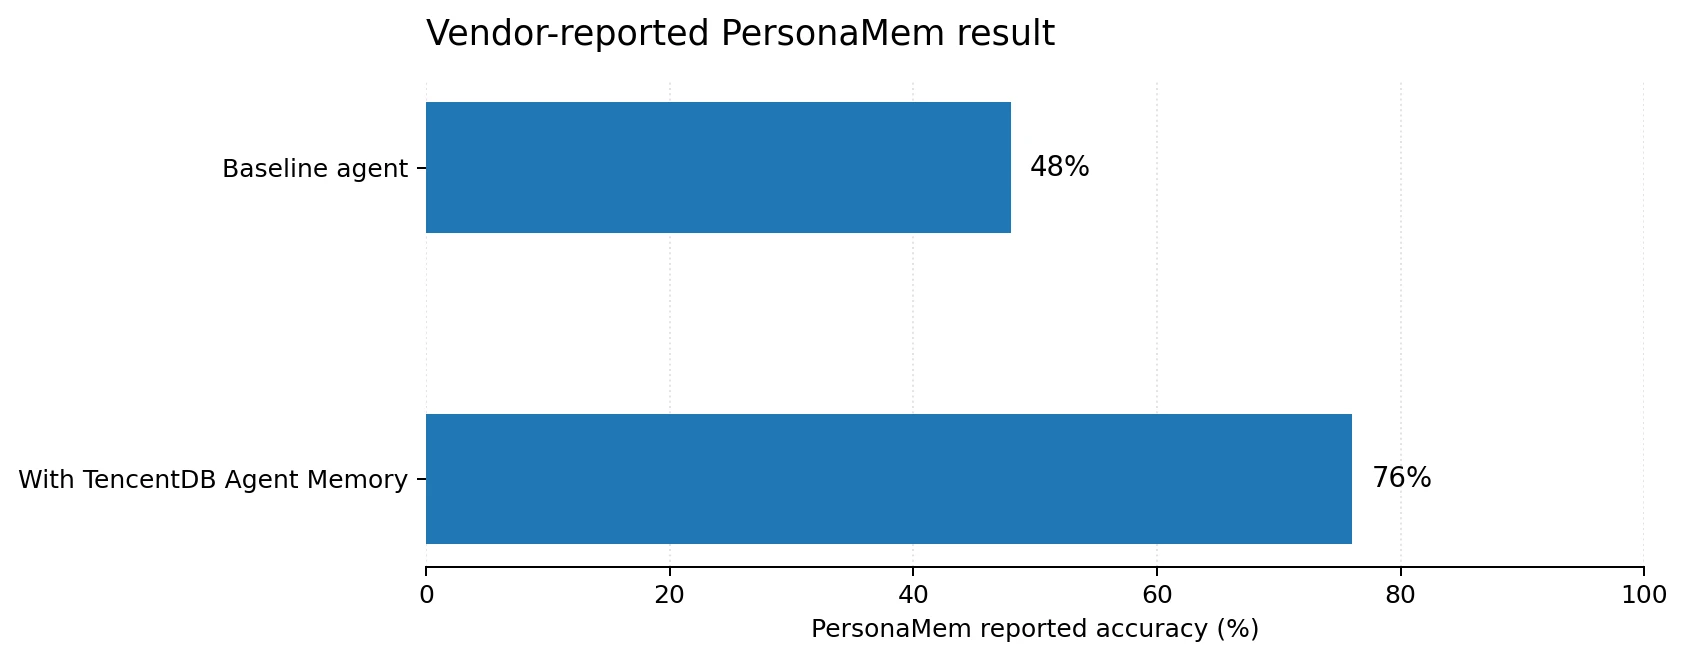
Initial benchmarks provided in the project’s documentation indicate a substantial performance boost. Using the PersonaMem scoring system, the project reported that agent performance rose from 48% to 76% when equipped with the memory stack—a relative improvement of approximately 58%. While these figures are internal to the project, they suggest a significant reduction in "hallucinations" and a higher rate of adherence to complex instructions.
Broader Industry Implications
The release of TencentDB Agent Memory as an open-source tool marks a pivotal moment for the DevOps and Site Reliability Engineering (SRE) communities. As companies increasingly integrate AI into their CI/CD pipelines and incident response workflows, the ability to maintain a "communal brain" for these agents becomes a competitive advantage.
For organizations, the implications are two-fold. First, it reduces the "onboarding time" for AI agents. Much like a new human hire, an agent with access to a team’s CodeGraph and incident history can become productive immediately. Second, it provides a layer of "organizational safety." By enforcing reviewed "Skills" and "LLM-Wiki" entries, companies can ensure that AI agents do not deviate from established security and operational standards.
However, the technology also introduces new responsibilities. The "lifecycle" of a memory means that stale or incorrect advice must be actively managed. If a team changes a protocol but fails to update the "Skill" in the Memory Core, the agent will continue to provide outdated guidance. This necessitates a new role within engineering teams: the "Memory Librarian" or "AI Knowledge Manager," responsible for auditing the facts and procedures the AI uses to make decisions.
Conclusion
TencentDB Agent Memory represents a shift away from the "stateless" nature of current LLM applications toward a more integrated, "stateful" ecosystem. By focusing on managed assets rather than just raw context, it provides a framework where engineering lessons are not lost at the end of a chat session. While the system requires a dedicated infrastructure—including Memory Core, Proxy, and Hub services—the potential for improved accuracy and team-wide collaboration is significant. As AI agents move closer to becoming true "digital colleagues," the ability to remember, share, and protect knowledge will be the defining characteristic of a successful deployment. Organizations looking to move beyond simple AI experimentation toward production-grade agentic workflows will find the TencentDB Agent Memory project a vital piece of the architectural puzzle.

 Asep Darmawan
 Nila Kartika Wati